You are designing a 5-node strongly consistent metadata store (etcd/Consul-style) using Raft across 3 availability zones (RTT 2 ms intra-AZ, 15 ms cross-AZ). During asymmetric network partitions and leader crashes, a naive implementation lost committed keys (the Raft Figure 8 anomaly) and served stale reads from deposed leaders. Design the Raft state transitions, commit rules, `ReadIndex` linearizable read path, and snapshotting invariants to guarantee zero split-brain and strict linearizability.
From patterns to decisions.
You are designing a 5-node strongly consistent metadata store (etcd/Consul-style) using Raft across 3 availability zones (RTT 2 ms intra-AZ, 15 ms cross-AZ). During asymmetric network partitions and leader crashes, a naive implementation lost committed keys (the Raft Figure 8 anomaly) and served stale reads from deposed leaders. Design the Raft state transitions, commit rules, `ReadIndex` linearizable read path, and snapshotting invariants to guarantee zero split-brain and strict linearizability.
An entry from an earlier.
An entry from an earlier term replicated to a majority can still be overwritten by a new leader whose log has a higher-term entry at an earlier index.
| Choice | What it buys | What it costs |
|---|---|---|
| Trade-off 1 | Requiring a `NO_OP` entry on leader election adds 1 quorum RTT (~15 ms) to failover before old entries commit. |
Step 1
Trace S1 writing entry at index 2 in term 2, crashing, and S5 getting elected in term 3.
Step 2
S1 recovers in term 4, replicates term-2 entry to S2/S3 (3/5 nodes).
Step 3
If S1 commits term-2 entry directly and crashes, S5 (term 3 > term 2) can still win election and overwrite index 2.
Alternative 1
None—this invariant is mandatory for Raft safety.
Failure Mode 1
Violating this rule causes silent data loss of acknowledged writes after double leader crashes.
def is_log_up_to_date(cand_last_term: int, cand_last_idx: int, my_last_term: int, my_last_idx: int) -> bool:
    if cand_last_term != my_last_term:
        return cand_last_term > my_last_term
    return cand_last_idx >= my_last_idx
Implementation & Guardrails (2).
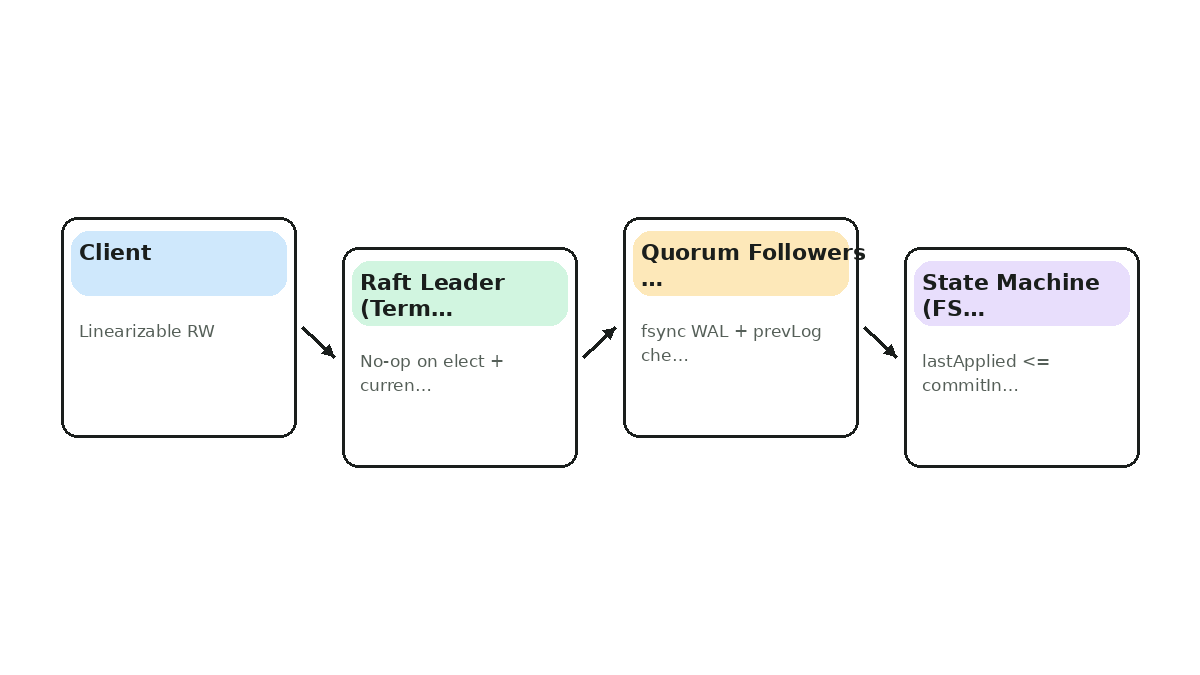
Verify prevLogIndex/prevLogTerm on followers and advance commitIndex only for currentTerm entries replicated on a majority.
| Choice | What it buys | What it costs |
|---|---|---|
| Trade-off 1 | Scanning backwards from `lastLogIndex` breaks immediately on the highest valid index, O(N) worst case. |
Step 1
In advanceCommitIndex, iterate N from lastLogIndex down to commitIndex + 1.
Step 2
Check log[N].term == currentTerm and count(matchIndex >= N) > N_NODES / 2.
Step 3
In handleAppendEntries, reject if term < currentTerm or prevLog mismatches.
Alternative 1
Sort matchIndex values and pick the median index in O(K log K) where K=clusterSize.
Failure Mode 1
Truncating a follower's log before verifying a conflict at the same index with a different term deletes valid entries.
public synchronized void advanceCommitIndex() {
    for (int n = log.size() - 1; n > commitIndex; n--) {
        if (log.get(n).term() != currentTerm) continue;
        int replicated = 1; // leader itself
        for (int match : matchIndex.values()) {
            if (match >= n) replicated++;
        }
        if (replicated > clusterSize / 2) {
            commitIndex = n;
            applyCommittedEntries();
            break;
        }
    }
}
ReadIndex is strictly safe under.
ReadIndex is strictly safe under arbitrary clock skew (15 ms RTT); LeaseRead hits 0.1 ms latency but requires bounded monotonic clock drift.
| Choice | What it buys | What it costs |
|---|---|---|
| Trade-off 1 | Batching `ReadIndex` coalesces 1,000 reads into 1 heartbeat RTT, achieving high throughput without clock assumptions. |
Step 1
Batch concurrent ReadIndex requests into a single quorum heartbeat round.
Step 2
Compare against LeaseRead using CLOCK_MONOTONIC bounded by electionTimeout / 2.
Alternative 1
Allow follower ReadIndex (etcd Serializable or follower-ask-leader-readIndex) to scale read CPU across all 5 nodes.
Failure Mode 1
VM live-migration pauses > electionTimeout break LeaseRead safety.
public String linearizableRead(String key) {
    long readIdx = this.commitIndex;
    if (!confirmQuorumHeartbeat()) {
        stepDown();
        throw new NotLeaderException();
    }
    waitUntilApplied(readIdx);
    return stateMachine.get(key);
}
PreVote blocks term inflation while.
PreVote blocks term inflation while partitioned; CheckQuorum forces a partitioned leader to step down within 1 election timeout.
| Choice | What it buys | What it costs |
|---|---|---|
| Trade-off 1 | Rejecting `PreVote` while `leader_recently_active` can delay a legitimate election by up to 1 `electionTimeout` if the leader just died. |
Step 1
Partitioned node sends PreVote without incrementing currentTerm.
Step 2
Healthy majority rejects PreVote because they recently heard from the active leader.
Step 3
Cluster avoids unnecessary leader step-down and election pause.
Alternative 1
Use LeaderTransfer RPC for planned maintenance step-downs (zero timeout wait).
Failure Mode 1
Without PreVote, a node with a one-way network fault increments term to 10,000 and forces healthy leader step-downs on reconnect.
def handle_pre_vote(cand_term: int, cand_last_term: int, cand_last_idx: int,
                    my_term: int, leader_recently_active: bool, my_log_tail: tuple[int, int]) -> bool:
    if leader_recently_active:
        return False
    if cand_term < my_term:
        return False
    return is_log_up_to_date(cand_last_term, cand_last_idx, my_log_tail[0], my_log_tail[1])
Retain a 10k-entry trailing WAL.
Retain a 10k-entry trailing WAL buffer after taking a snapshot, and stream InstallSnapshot in 1 MB chunks with flow control.
| Choice | What it buys | What it costs |
|---|---|---|
| Trade-off 1 | Keeping 10k trailing entries uses ~5 MB extra disk, avoiding expensive 500 MB snapshot transfers for brief follower restarts. |
Step 1
Take non-blocking copy-on-write snapshot of FSM at lastApplied.
Step 2
Keep max(0, snapshotIdx - 10000) in WAL so minor lags use normal AppendEntries.
Step 3
Stream InstallSnapshot chunks asynchronously with offset tracking.
Alternative 1
Rate-limit InstallSnapshot bandwidth (e.g., 50 MB/s) to protect foreground AppendEntries latency.
Failure Mode 1
Deleting WAL up to snapshot_idx synchronously blocks the Raft loop if snapshot serialization isn't copy-on-write.
def compact_wal(wal: list, snapshot_idx: int, keep_tail: int = 10000) -> int:
    truncate_to = max(0, snapshot_idx - keep_tail)
    del wal[:truncate_to]
    return truncate_to
Theory & Tips and Tricks
Practical heuristics & interview traps
- 01Interview anchor: Never commit log entries from a previous term by counting replicas alone (Figure 8 bug); a leader may only advance
commitIndexfor entries from itscurrentTerm, and linearizable reads requireReadIndexquorum heartbeats. - 02Trade-off tip: Batching
ReadIndexcoalesces 1,000 reads into 1 heartbeat RTT, achieving high throughput without clock assumptions. - 03Watch out for: Without
PreVote, a node with a one-way network fault increments term to 10,000 and forces healthy leader step-downs on reconnect.
Raft Consensus Safety Invariants — Normal → Load / Fault → Recovery
Never commit log entries from a previous term by counting replicas alone (Figure 8 bug); a leader may only advance commitIndex for entries from its currentTerm, and linearizable reads require ReadIndex quorum heartbeats.
Putting Raft Consensus & Leader Election Safety Together
Never commit log entries from a previous term by counting replicas alone (Figure 8 bug); a leader may only advance `commitIndex` for entries from its `currentTerm`, and linearizable reads require `ReadIndex` quorum heartbeats.
Putting Raft Consensus & Leader Election Safety Together
- In
advanceCommitIndex, iterateNfromlastLogIndexdown tocommitIndex + 1. - Check
log[N].term == currentTermandcount(matchIndex >= N) > N_NODES / 2. - In
handleAppendEntries, reject ifterm < currentTermorprevLogmismatches.
Interview Readiness Check
PreVote blocks term inflation while partitioned; CheckQuorum forces a partitioned leader to step down within 1 election timeout.
Walk through bottlenecks, back-of-the-envelope math, and failure recovery.
Make the trade-off yourself.
Practice Check
Test your understanding
When is Split-Brain Prevention the right default for a production team?
Raft Consensus & Leader Election Safety
Never commit log entries from a previous term by counting replicas alone (Figure 8 bug); a leader may only advance commitIndex for entries from its currentTerm, and linearizable reads require ReadIndex quorum heartbeats.