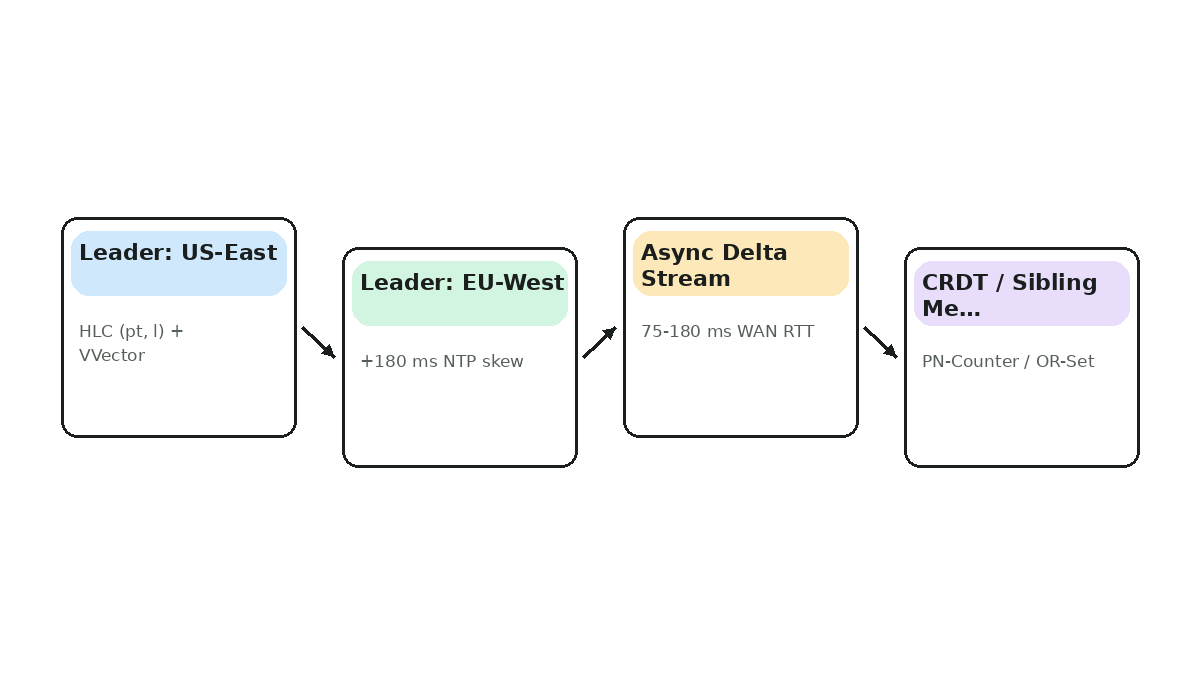
Your active-active multi-region platform runs 3 regional leaders (US-East, EU-West, AP-South) handling 15,000 writes/sec for user shopping carts, feature toggles, and inventory counters. Asynchronous cross-region replication resolves concurrent updates via Last-Write-Wins (LWW) using `System.currentTimeMillis()`. Because of a +180 ms NTP drift on an EU-West node, an EU write occurring 100 ms *after* (or *before*) a US-East write carries a higher timestamp and silently overwrites newer US-East updates—losing ~0.4% of concurrent updates (60 lost updates/sec) with zero error logs. Redesign the conflict-resolution protocol.
From patterns to decisions.
Your active-active multi-region platform runs 3 regional leaders (US-East, EU-West, AP-South) handling 15,000 writes/sec for user shopping carts, feature toggles, and inventory counters. Asynchronous cross-region replication resolves concurrent updates via Last-Write-Wins (LWW) using `System.currentTimeMillis()`. Because of a +180 ms NTP drift on an EU-West node, an EU write occurring 100 ms *after* (or *before*) a US-East write carries a higher timestamp and silently overwrites newer US-East updates—losing ~0.4% of concurrent updates (60 lost updates/sec) with zero error logs. Redesign the conflict-resolution protocol.
At real time t=1000 ms.
At real time t=1000 ms, EU writes with skewed clock t_eu=1180 ms. US reads it at t=1080 ms and writes a dependent update stamped t_us=1090 ms. LWW sees 1180 > 1090 and discards US's newer causal write.
| Choice | What it buys | What it costs |
|---|---|---|
| Trade-off 1 | Even with 0 ms clock skew, concurrent writes at the exact same millisecond still lose one update under LWW. |
Step 1
Trace the causal chain EU_write -> US_read -> US_write.
Step 2
Show how 1180 > 1090 violates happens-before.
Alternative 1
Single-leader or Spanner TrueTime if strict linearizability is mandatory.
Failure Mode 1
Zero error logs are emitted when LWW drops a write, making data loss invisible until customer complaints.
eu_write_ts = 1000 + 180  # +180ms NTP skew
us_causal_write_ts = 1090
winner = max(eu_write_ts, us_causal_write_ts)
assert winner == eu_write_ts  # Newer causal US write is silently lost!
Combine an HLC (now() and.
Combine an HLC (now() and receive(remote_pt, remote_l)) with a PN-Counter / OR-Set merge so causal writes advance monotonically and concurrent updates converge.
| Choice | What it buys | What it costs |
|---|---|---|
| Trade-off 1 | If a rogue node's physical clock jumps +1 hour into the future, HLC `pt` latches to +1 hour until bounded by max-drift rejection. |
Step 1
Implement HLC.local_event() and HLC.receive(msg_pt, msg_l).
Step 2
Implement ORSet.merge(other) keeping additions whose unique (region, hlc) tags are not in removed_tags.
Alternative 1
In Java, pack (pt << 16) | (l & 0xFFFF) into a single 64-bit long for atomic DB column comparison.
Failure Mode 1
Accepting an arbitrary msg_pt without checking abs(msg_pt - wall) < max_skew_ms allows one broken NTP node to pull the whole cluster's HLC forward.
import time

class HLC:
    def __init__(self):
        self.pt = 0
        self.l = 0

    def local_event(self) -> tuple[int, int]:
        wall = int(time.time() * 1000)
        if wall > self.pt:
            self.pt, self.l = wall, 0
        else:
            self.l += 1
        return (self.pt, self.l)

    def receive(self, msg_pt: int, msg_l: int) -> tuple[int, int]:
        wall = int(time.time() * 1000)
        prev_pt = self.pt
        self.pt = max(prev_pt, msg_pt, wall)
        if self.pt == prev_pt == msg_pt:
            self.l = max(self.l, msg_l) + 1
        elif self.pt == prev_pt:
            self.l += 1
        elif self.pt == msg_pt:
            self.l = msg_l + 1
        else:
            self.l = 0
        return (self.pt, self.l)
Routing EU and AP writes.
Routing EU and AP writes to US-East adds 75–180 ms RTT per write and breaks write availability during WAN partitions. CRDTs preserve 15 ms local writes and zero-loss convergence.
| Choice | What it buys | What it costs |
|---|---|---|
| Trade-off 1 | CRDTs cannot enforce a global non-negative cap (`value >= 0`) without cross-region reservation. |
Step 1
Compare local write latency (<15 ms) vs cross-region RTT (75–180 ms).
Step 2
Reserve single-leader/home-region routing strictly for hard-invariant operations like payment capture.
Alternative 1
Pre-allocate regional inventory quotas (e.g., 100 units to US, 100 to EU) to keep local writes conflict-free.
Failure Mode 1
Using LWW on a PN-Counter's map instead of max() per region slot reintroduces lost increments.
class PNCounter:
    def __init__(self):
        self.p, self.n = {}, {}
    def inc(self, region: str, val: int = 1):
        self.p[region] = self.p.get(region, 0) + val
    def value(self) -> int:
        return sum(self.p.values()) - sum(self.n.values())
    def merge(self, other: 'PNCounter'):
        for r, v in other.p.items(): self.p[r] = max(self.p.get(r, 0), v)
        for r, v in other.n.items(): self.n[r] = max(self.n.get(r, 0), v)
Enforce a max_clock_offset_ms = 500.
Enforce a max_clock_offset_ms = 500 guard on HLC.receive(): if msg_pt - wall > 500, reject/quarantine replication from that node and alert on NTP drift.
| Choice | What it buys | What it costs |
|---|---|---|
| Trade-off 1 | Quarantining a drifting node temporarily delays its replication until NTP steps the clock back. |
Step 1
Compare msg_pt - wall against 500 ms threshold.
Step 2
Log/quarantine skewed messages and fence the drifting node until NTP resyncs.
Alternative 1
Use AWS Time Sync / Google TrueTime hardware clocks to keep drift < 1 ms.
Failure Mode 1
Stepping an OS clock backward without HLC breaks monotonic timestamps; always use chrony slew mode.
MAX_SKEW_MS = 500
if msg_pt - wall > MAX_SKEW_MS:
    raise ValueError(f'Clock skew {msg_pt - wall}ms exceeds {MAX_SKEW_MS}ms; quarantining node')
Implementation & Guardrails (5).
Use causal-context compaction (Observed-Remove Without Tombstones / Dotted Version Vectors) or periodically prune tombstones older than the max anti-entropy convergence window (e.g., 7 days).
| Choice | What it buys | What it costs |
|---|---|---|
| Trade-off 1 | A region offline longer than 7 days must full-sync rather than delta-sync after tombstone GC. |
Step 1
Track a global stability watermark across all 3 regions.
Step 2
Drop remove-tags whose HLC is below the minimum watermark across all regions.
Alternative 1
Reset/archive cart state on checkout completion.
Failure Mode 1
GC'ing tombstones before a partitioned region syncs causes deleted cart items to resurrect.
# Stability watermark: min(last_acked_hlc across US, EU, AP)
# Any tombstone tag with hlc < stability_watermark can be safely GC'd.
Theory & Tips and Tricks
Practical heuristics & interview traps
- 01Interview anchor: Eliminate LWW silent data loss by replacing physical wall-clock LWW with Hybrid Logical Clocks (HLC) plus Dotted Version Vectors for conflict detection, and use CRDTs (PN-Counter / OR-Set) or per-key home-region routing for concurrent mutations.
- 02Trade-off tip: CRDTs cannot enforce a global non-negative cap (
value >= 0) without cross-region reservation. - 03Watch out for: Stepping an OS clock backward without HLC breaks monotonic timestamps; always use
chronyslew mode.
Multi Leader Conflict Resolution Crdts — Normal → Load / Fault → Recovery
Eliminate LWW silent data loss by replacing physical wall-clock LWW with Hybrid Logical Clocks (HLC) plus Dotted Version Vectors for conflict detection, and use CRDTs (PN-Counter / OR-Set) or per-key home-region routing for concurrent mutations.
Putting Multi-Leader Conflicts: Beyond Last-Write-Wins Together
Eliminate LWW silent data loss by replacing physical wall-clock LWW with Hybrid Logical Clocks (HLC) plus Dotted Version Vectors for conflict detection, and use CRDTs (PN-Counter / OR-Set) or per-key home-region routing for concurrent mutations.
Putting Multi-Leader Conflicts: Beyond Last-Write-Wins Together
- Implement
HLC.local_event()andHLC.receive(msg_pt, msg_l). - Implement
ORSet.merge(other)keeping additions whose unique(region, hlc)tags are not inremoved_tags.
Interview Readiness Check
Enforce a max_clock_offset_ms = 500 guard on HLC.receive(): if msg_pt - wall > 500, reject/quarantine replication from that node and alert on NTP drift.
Walk through bottlenecks, back-of-the-envelope math, and failure recovery.
Make the trade-off yourself.
Practice Check
Test your understanding
When is ACID Transaction Fundamentals the right default for a production team?
Multi-Leader Conflicts: Beyond Last-Write-Wins
Eliminate LWW silent data loss by replacing physical wall-clock LWW with Hybrid Logical Clocks (HLC) plus Dotted Version Vectors for conflict detection, and use CRDTs (PN-Counter / OR-Set) or per-key home-region routing for concurrent mutations.